·
5 minute read
In the previous articles in this series, we explored the core observability tools for metrics, logs, and traces, then took a closer look at the agents and collectors that gather telemetry data. Now it is time to put theory into practice. In this article, we will walk through collecting application logs running on Kubernetes using Fluent Bit as the log collector and Grafana Loki as the log storage backend.
What We Will Build
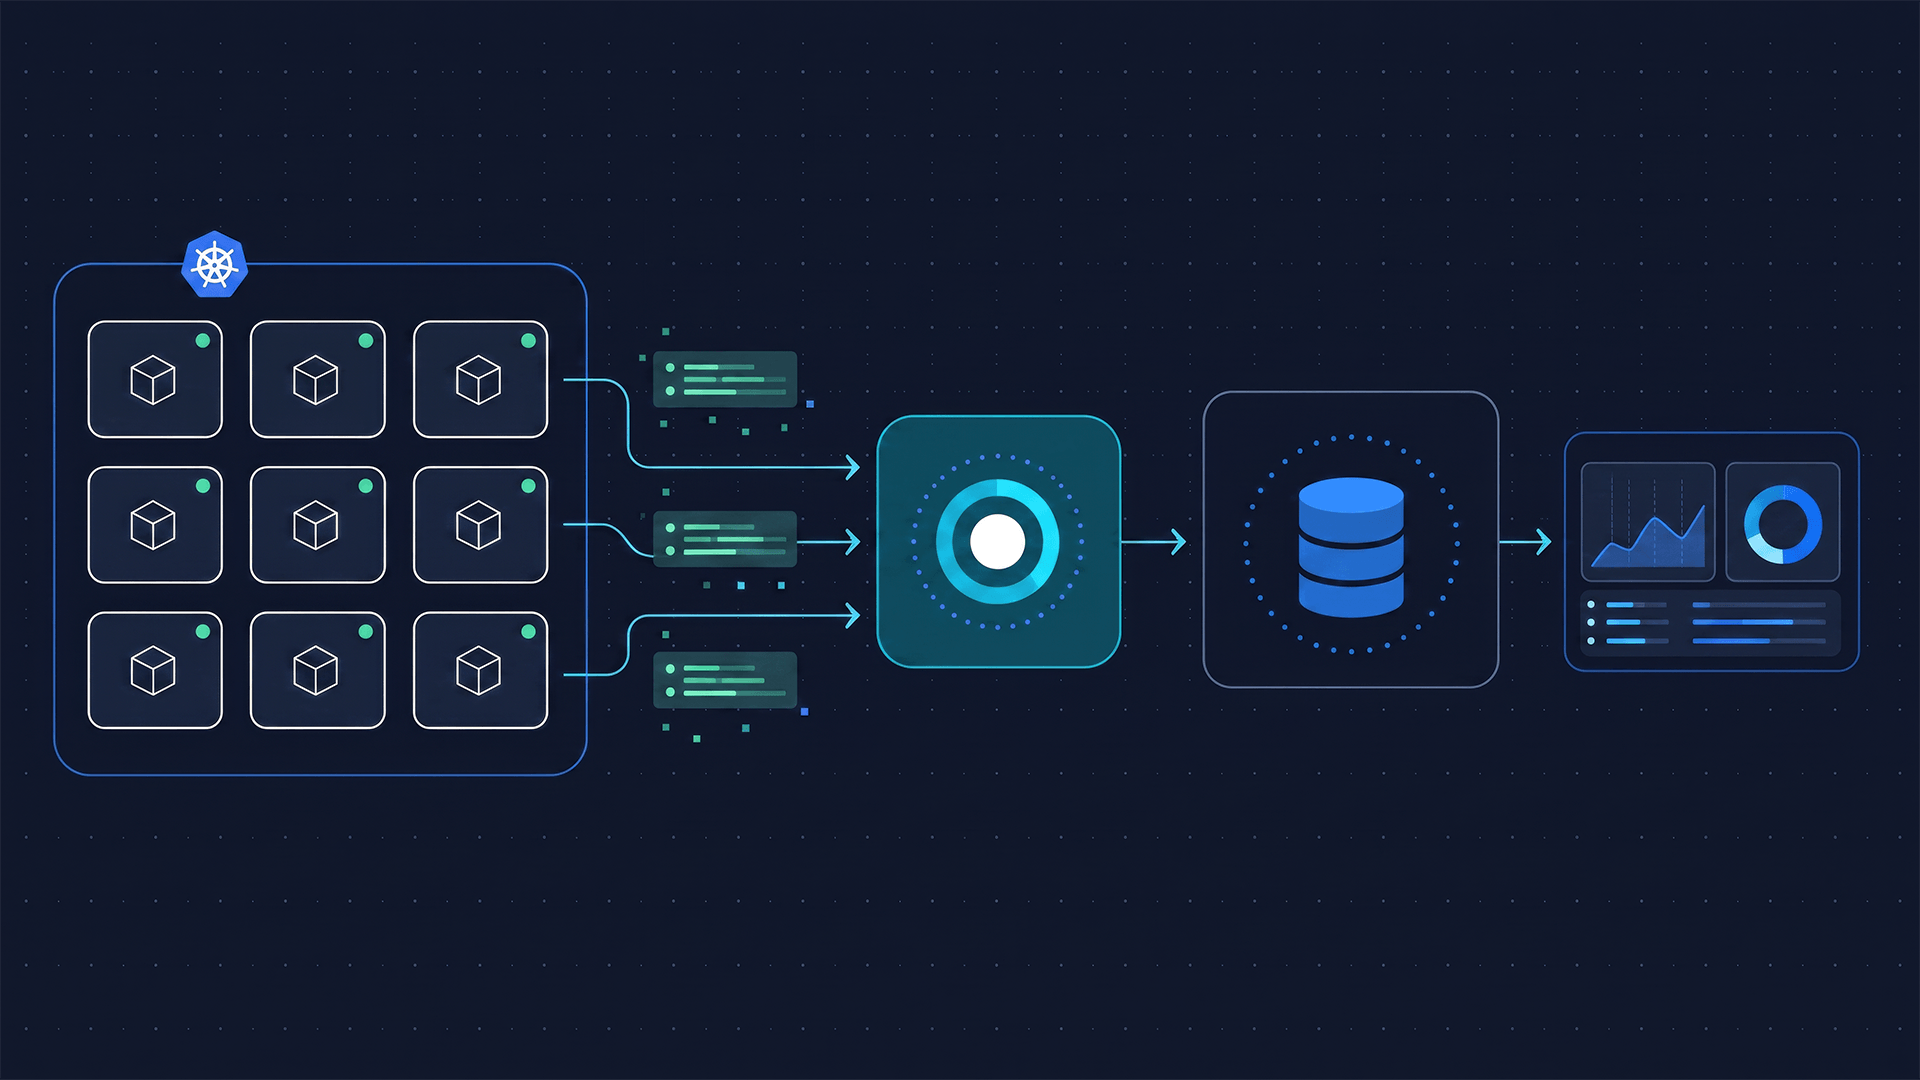
In this demo, we will set up a complete log collection pipeline on a local Kubernetes cluster using Minikube. Fluent Bit will run as a DaemonSet on each node to collect container logs and forward them to Loki. Loki will store log data in GarageHQ, a lightweight self-hosted S3-compatible object storage, instead of local disk. Finally, Grafana will query and visualize the logs stored in Loki.
Demo
Start Minikube
minikube start
GarageFS
Garage is a lightweight geo-distributed data store that implements the Amazon S3 object storage protocol. It enables applications to store large blobs such as pictures, video, images, and documents in a redundant multi-node setting.
helm upgrade --install garage-operator oci://ghcr.io/rajsinghtech/charts/garage-operator \
  --namespace hepapi-monitoring \
  --create-namespace --version 0.2.2

kubectl create secret generic garage-admin-token --namespace hepapi-monitoring \
  --from-literal=admin-token=$(openssl rand -hex 32)
Install GarageFS Cluster
apiVersion: garage.rajsingh.info/v1alpha1
kind: GarageCluster
metadata:
  name: garage
  namespace: hepapi-monitoring
spec:
  replicas: 1
  zone: us-east-1
  replication:
    factor: 1
  storage:
    data:
      size: 4Gi
  network:
    rpcBindPort: 3901
    service:
      type: ClusterIP
  admin:
    enabled: true
    bindPort: 3903
    adminTokenSecretRef:
      name: garage-admin-token
      key: admin-token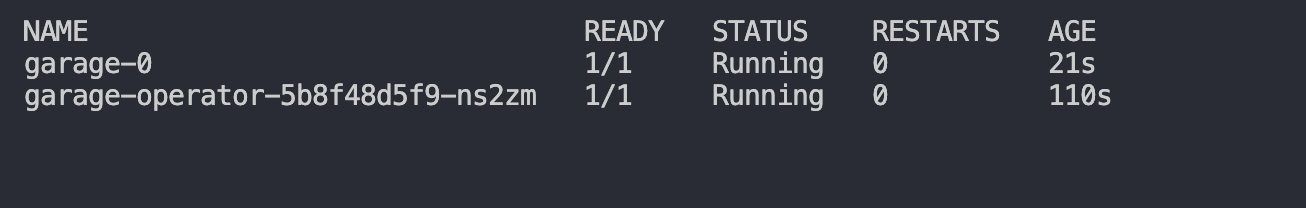
Create Buckets for Loki Storage
apiVersion: garage.rajsingh.info/v1alpha1
kind: GarageBucket
metadata:
  name: loki-chunks
  namespace: hepapi-monitoring
spec:
  clusterRef:
    name: garage
  quotas:
    maxSize: 2Gi
---
apiVersion: garage.rajsingh.info/v1alpha1
kind: GarageBucket
metadata:
  name: loki-ruler
  namespace: hepapi-monitoring
spec:
  clusterRef:
    name: garage
  quotas:
    maxSize: 1Gi
Create Admin-key for All Buckets
apiVersion: garage.rajsingh.info/v1alpha1
kind: GarageKey
metadata:
  name: admin-key
  namespace: hepapi-monitoring
spec:
  clusterRef:
    name: garage
  allBuckets:
    read: true
    write: true
    owner: true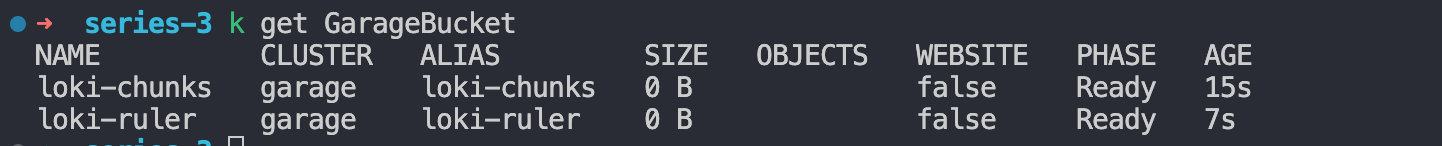
Install Loki
In the first article of this series, we covered Loki's deployment modes in detail. For this demo, we will use the single binary (monolithic) mode, which runs all Loki components in a single process and is well suited for local and small-scale setups. If you need a refresher on deployment modes, you can refer back to the first article.
deploymentMode: SingleBinary

loki:
  auth_enabled: false
  commonConfig:
    replication_factor: 1
  schemaConfig:
    configs:
      - from: "2025-06-01"
        store: tsdb
        object_store: s3
        schema: v13
        index:
          prefix: loki_index_
          period: 24h
  compactor:
    compaction_interval: 10m
    working_directory: /tmp/compactor
    retention_enabled: true
    retention_delete_delay: 2h
    delete_request_store: s3
  limits_config:
    allow_structured_metadata: true
    retention_period: 48h # 2 days
  storage_config:
    tsdb_shipper:
      active_index_directory: /var/loki/index
      cache_location: /var/loki/index_cache
      cache_ttl: 24h
  storage:
    type: s3
    s3:
      endpoint: http://garage.hepapi-monitoring.svc.cluster.local:3900
      region: garage
      secretAccessKey:  #update me
      accessKeyId:  #update me
      s3ForcePathStyle: true
      insecure: true
    bucketNames:
      chunks: loki-chunks
      ruler: loki-ruler

singleBinary:
  replicas: 1
  resources:
    requests:
      cpu: "500m"
      memory: "1000Mi"
    limits:
      cpu: "500m"
      memory: "1000Mi"

gateway:
  enabled: true

# Disable other deployment modes
backend:
  replicas: 0
read:
  replicas: 0
write:
  replicas: 0
distributor:
  replicas: 0
ingester:
  replicas: 0
querier:
  replicas: 0
queryFrontend:
  replicas: 0
queryScheduler:
  replicas: 0
ruler:
  replicas: 0
compactor:
  replicas: 0
indexGateway:
  replicas: 0
chunksCache:
  enabled: false
resultsCache:
  enabled: false
lokiCanary:
  enabled: false
test:
  enabled: false
Update the accessKeyId and secretAccessKey fields in your values.yaml with the values obtained from the commands below.
s3:
  endpoint: http://garage.hepapi-monitoring.svc.cluster.local:3900
  region: garage
  secretAccessKey:
  accessKeyId:
  s3ForcePathStyle: true
  insecure: true
echo "accessKeyId: $(kubectl get secret admin-key -n hepapi-monitoring -o jsonpath='{.data.access-key-id}' | base64 -d)"
echo "secretAccessKey: $(kubectl get secret admin-key -n hepapi-monitoring -o jsonpath='{.data.secret-access-key}' | base64 -d)"Update the retention_period field based on your needs. For this demo, we set it to 48h.
limits_config:
  allow_structured_metadata: true
  retention_period: 48h
helm repo add grafana https://grafana.github.io/helm-charts
helm upgrade --install loki grafana/loki --version 6.38.0 -n hepapi-monitoring --create-namespace -f loki-values.yaml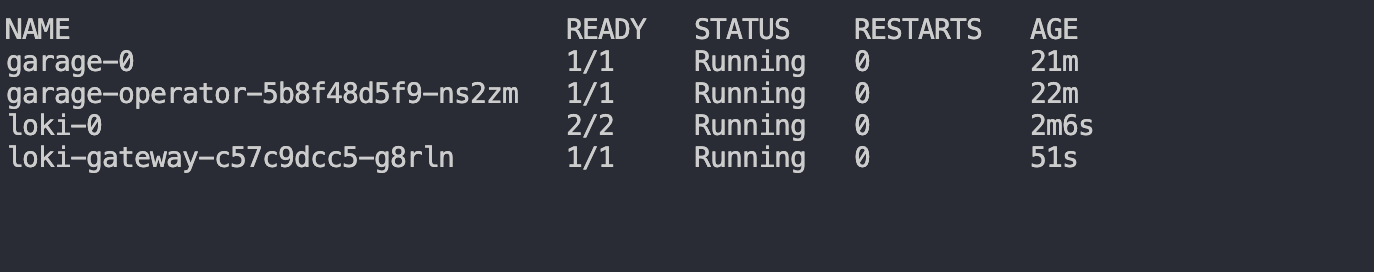
Install Grafana
We will install Grafana using Helm and configure Loki as a data source so we can query and explore our application logs directly from the Grafana UI.
adminUser: admin
adminPassword: hepapi-monitoring
replicas: 1
persistence:
  enabled: false
datasources:
  datasources.yaml:
    apiVersion: 1
    datasources:
    - name: Loki
      type: loki
      uid: loki
      url: http://loki-gateway
      access: proxy
      isDefault: false
helm repo add grafana https://grafana.github.io/helm-charts
helm upgrade --install grafana grafana/grafana -n hepapi-monitoring --version 10.5.15 -f grafana-values.yamlOnce the Grafana pod is ready, you can access the UI by running the following command and navigating to http://localhost:3000 in your browser.
kubectl port-forward svc/grafana 3000:80 -n hepapi-monitoring

user: admin
password: hepapi-monitoring
Install Fluent Bit
With Loki up and running, the next step is to deploy Fluent Bit. We will install it using Helm as a DaemonSet, so it runs on every node in the cluster and collects logs from all running containers.
kind: DaemonSet
logLevel: info
metricsPort: 2020
flush: 1
config:
  service: |
    [SERVICE]
        Daemon Off
        Flush
        Log_Level
        Parsers_File /fluent-bit/etc/parsers.conf
        Parsers_File /fluent-bit/etc/conf/custom_parsers.conf
        HTTP_Server On
        HTTP_Listen 0.0.0.0
        HTTP_Port
        Health_Check On

  inputs: |
    [INPUT]
        Name tail
        Path /var/log/containers/*.log
        multiline.parser docker, cri
        parser docker_no_time
        Tag kube.*
        Mem_Buf_Limit 5MB
        Skip_Long_Lines On

  filters: |
    [FILTER]
        Name kubernetes
        Match kube.*
        Merge_Log On
        Keep_Log Off
        K8S-Logging.Parser On
        K8S-Logging.Exclude On

    [FILTER]
        Name grep
        Match kube.*
        Regex $kubernetes['namespace_name'] app

  outputs: |
    [OUTPUT]
        name  loki
        match kube.*
        host  loki-gateway
        port  80
        labels  cluster=minikube,service_namespace=$kubernetes['namespace_name'],service_name=$kubernetes['labels']['app'],detected_level=$level

  customParsers: |
    [PARSER]
        Name docker_no_time
        Format json
        Time_Keep Off
        Time_Key time
        Time_Format %Y-%m-%dT%H:%M:%S.%L
helm repo add fluent https://fluent.github.io/helm-charts
helm upgrade --install fluent-bit fluent/fluent-bit --version 0.57.6 -f fluentbit.yaml -n hepapi-monitoringIn a real cluster, not every log is worth storing. System components, internal controllers, and noisy namespaces can quickly inflate your storage costs and make debugging harder. Fluent Bit's grep filter gives you fine-grained control over which logs are forwarded to Loki.
You can include only the namespaces you care about:
[FILTER]
    Name grep
    Match kube.*
    Regex $kubernetes['namespace_name'] ^(app|prod|staging)$
Or you can exclude namespaces you want to ignore:
[FILTER]
    Name grep
    Match kube.*
    Exclude $kubernetes['namespace_name'] ^(kube-system|calico-system|default)$
In this demo, we use the first approach and collect logs only from the app namespace where our sample application is running.
Deploy Sample Log Pod
To verify that our log pipeline is working end-to-end, we will deploy a simple sample application that continuously outputs JSON-formatted logs at different levels. The application uses the busybox image and alternates between info- and warn-level messages, allowing us to test our Fluent Bit filters and confirm that logs flow into Loki correctly.
apiVersion: v1
kind: Pod
metadata:
  name: json-logger
  namespace: prod
  labels:
    app: json-logger
spec:
  containers:
    - name: json-logger
      image: busybox
      command: ["sh", "-c"]
      args:
        - |
          while true; do
            echo "{\"level\":\"info\",\"message\":\"hello from json-logger\",\"timestamp\":\"$(date -u +%Y-%m-%dT%H:%M:%SZ)\"}"
            sleep 3
            echo "{\"level\":\"warn\",\"message\":\"something might be wrong\",\"timestamp\":\"$(date -u +%Y-%m-%dT%H:%M:%SZ)\"}"
            sleep 3
          done
kubectl create ns app
kubectl apply -f sample-log-pod.yaml
Verify Logs in Grafana
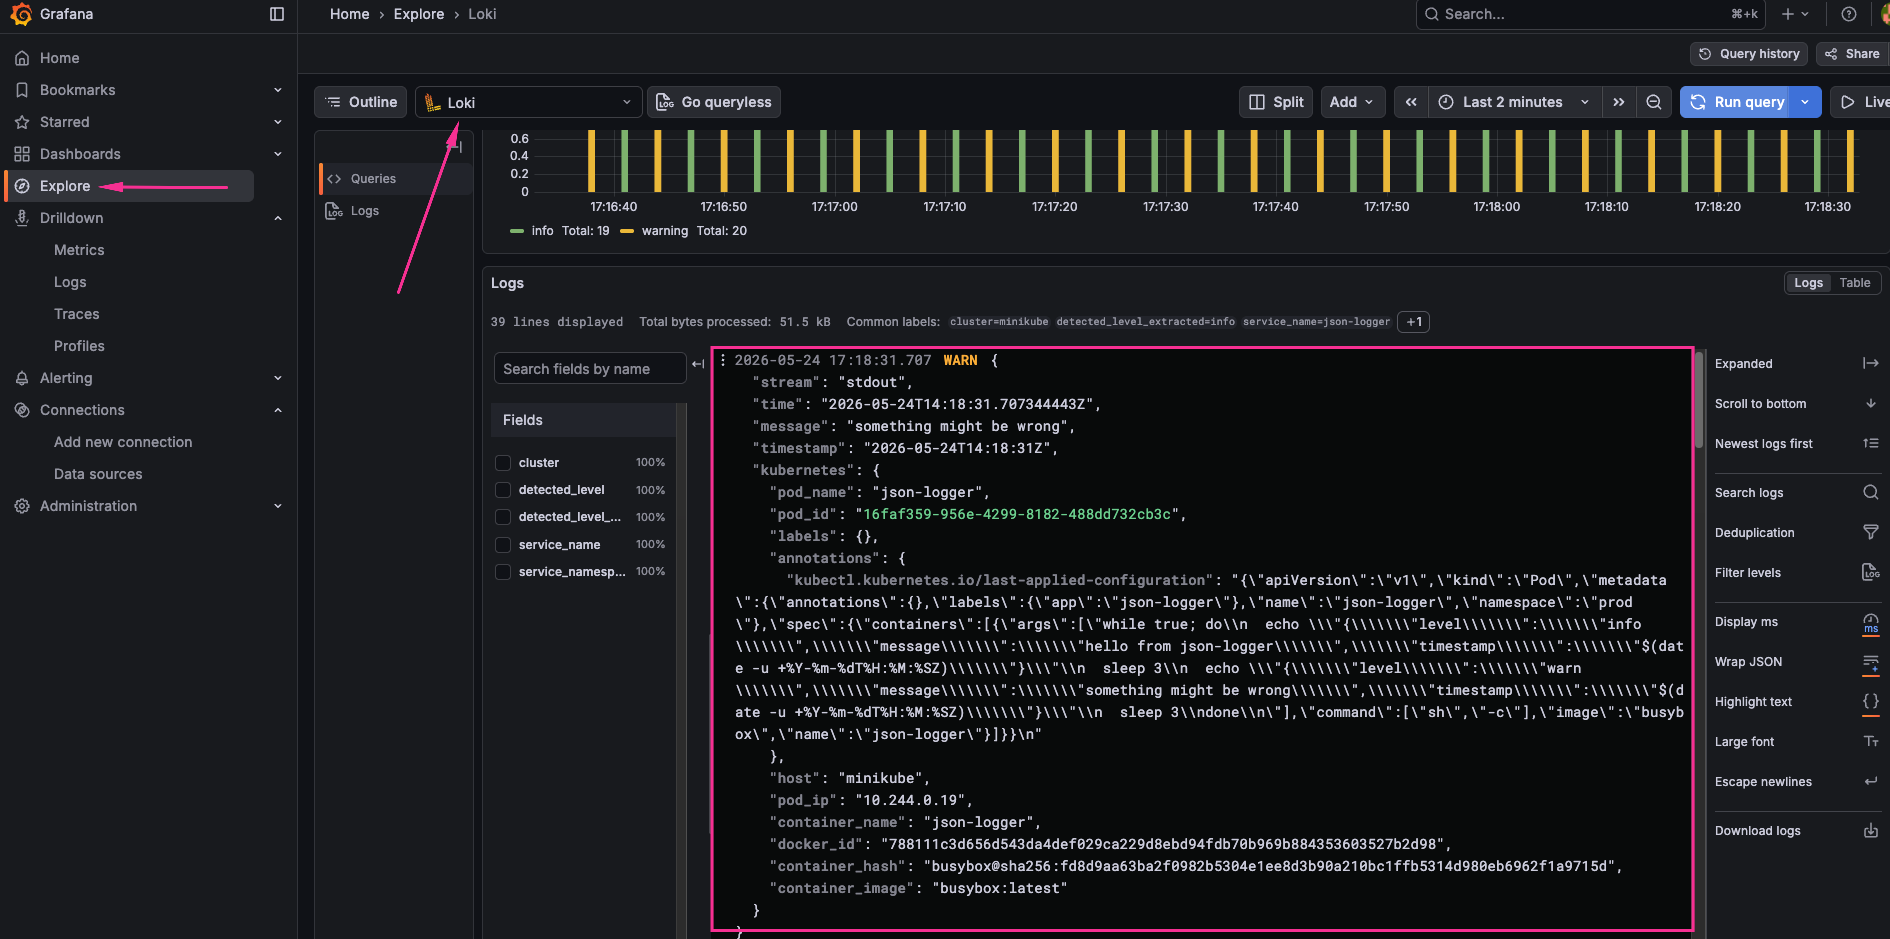
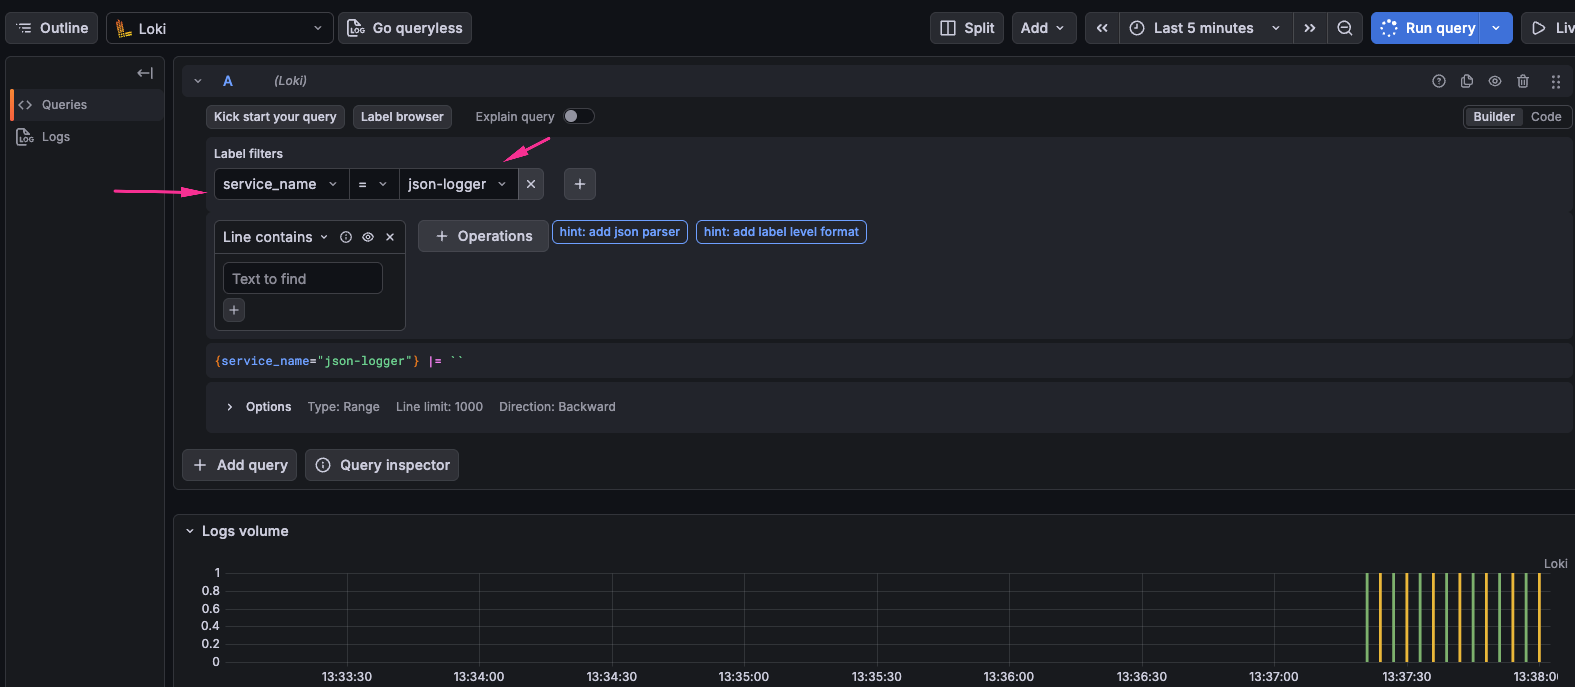
Once the application is running and generating logs, navigate to Grafana and click on Explore from the left menu. Select Loki as the data source, then use the label filters to query your logs. You can filter by cluster, service_name, or service_namespace to narrow down the results and confirm that logs are flowing through the pipeline correctly.
Dropping Unwanted Fields
Even after filtering by namespace, individual log records may still contain fields you do not need, such as stream. Storing these unnecessary fields wastes storage and adds noise when querying logs. You can use the record_modifier filter to remove specific fields before logs are forwarded to Loki.
[FILTER]
    Name record_modifier
    Match kube.*
    Remove_key stream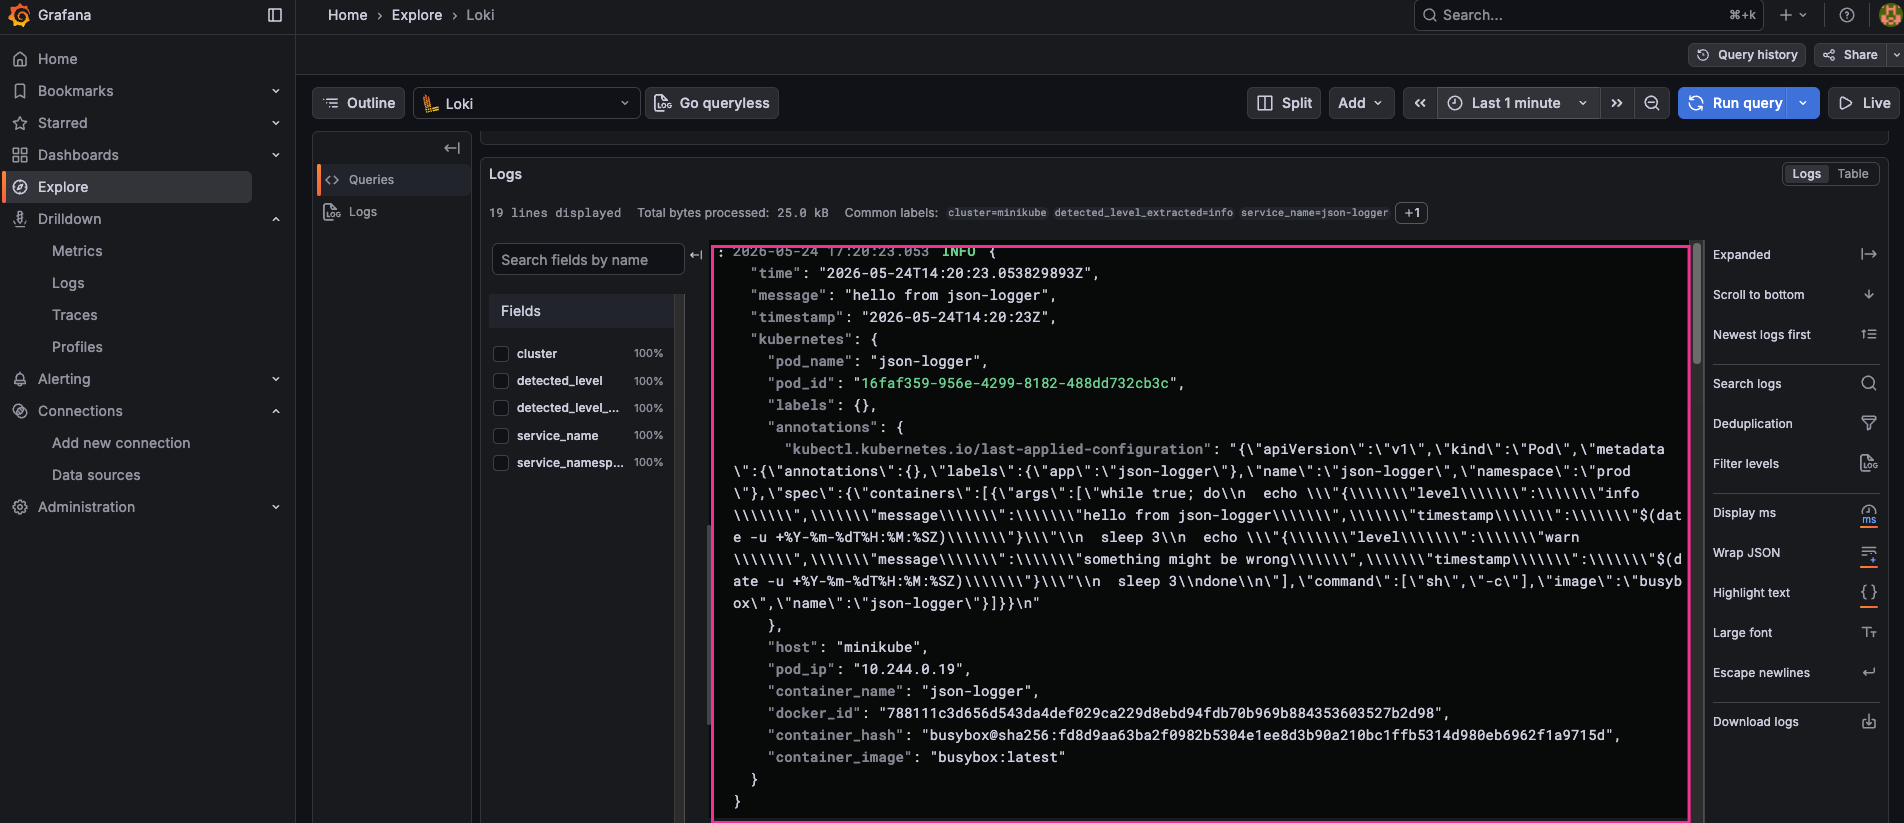
Conclusion
In this article, we walked through a complete log collection pipeline on Kubernetes from the ground up. We deployed GarageFS as a lightweight S3-compatible object storage backend, configured Loki in single binary mode to persist logs in GarageFS buckets, and set up Fluent Bit as a DaemonSet to collect container logs from every node in the cluster. Finally, we connected everything to Grafana for querying and visualization.
It is worth noting that in this demo, GarageFS was deployed inside the same Kubernetes cluster purely for simplicity. In a production environment, this approach is not recommended. If your infrastructure runs on a cloud provider, use a managed object storage service such as AWS S3, Google Cloud Storage, or Azure Blob Storage instead. For on-premises setups, deploy GarageFS on dedicated virtual machines outside the cluster, with multiple nodes for high availability. Either way, keeping your storage layer independent from the cluster protects log data from cluster failures and avoids resource contention.
In the next article, we will explore another popular approach to log collection and storage using Filebeat and Elasticsearch deployed with the Elastic Cloud on Kubernetes (ECK) operator.